
Best practices for AI across the evaluation lifecycle
Reflections from a recent Bond workshop
In May, BOND hosted a MEL and AI Workshop, which brought together 25 practitioners to explore how Generative AI can be applied across monitoring, evaluation and learning (MEL), facilitated by Kerry Bruce (ClearUp Consulting) and Linda Raftree (MERL Tech Initiative). Participants were introduced to real-world applications of AI across the evaluation lifecycle, as well as key considerations around data protection, safeguarding and responsible use. Below is a snapshot of the session.
AI tools support different stages of the MEL cycle. The strongest applications are currently in design, planning, analysis and reporting.
Where AI adds the most value:
- Summarising long reports into accessible formats
- Classifying and analysing qualitative data (e.g., sentiment analysis)
- Extracting key information from large datasets
- Supporting translation and transcription
- Identifying patterns across multiple data sources
- Acting as a thought partner for writing and analysis
Where AI is weaker:
- Stakeholder management and relationship-driven tasks
- Primary data collection
- Judgement-heavy and context-sensitive decisions
- Utilisation and follow-through
Climate and conservation: Large language models vs small language models
Large language models carry significant energy, water and environmental costs. For climate-conscious organisations, small language models are worth considering.
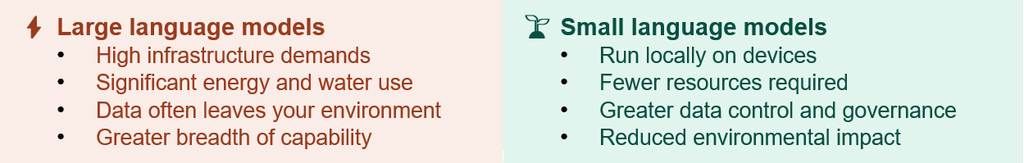
🛠 Tools used by MEL practitioners
| Tool | Use case | Level |
|---|---|---|
| ChatGPT / Claude | Structuring, analysis, drafting outputs | Beginner–Mid |
| Google Workspace / MS Copilot | Integrated writing, analysis and workflow support within existing systems | Beginner–Mid |
| NotebookLM | Organising information, transforming outputs (e.g., podcasts, visuals) | Intermediate |
| AIlyze | Qualitative data analysis — recommended in session | Intermediate |
| Julius AI | Data integration and analysis | Advanced |
| Across the examples given, real-world impact has been seen in programmes and organisations. AI tools have reduced time for analysis and reporting from months to days, enabled new formats for communicating findings (e.g., podcasts, infographics), and supported evidence use through searchable knowledge systems such as UNICEF/UNDP AIDAs. However, there are key considerations around completeness, accuracy and responsible use. We focus on responsible use below. |
🛡 Responsible use of AI
A key takeaway from the session was the importance of understanding bias in AI systems.
Common forms of bias in AI systems include:
Historical bias
Bias rooted in historical inequalities (e.g., gender, race, disability) baked into the data used to ‘train’ AI.
Representational bias
Training data over-represents Global North contexts, leading to worse performance for underrepresented communities.
Semantic bias
This relates to language-based stereotyping, where word associations encode cultural assumptions (e.g., gendered job titles).
Label and algorithm bias
Errors introduced by humans who labelled training data, or by algorithms that encode structural inequalities.
Automation bias
The tendency to over-trust AI outputs without critical review — a particular risk when working quickly or under pressure.
These biases are especially relevant in international development, where the communities development organisations work with are often underrepresented in training data. Good practice is to always maintain a human in the loop.
Mitigating bias: human-in-the-loop practices
- Spot-check AI-generated outputs regularly
- Explicitly review AI-generated outputs for bias before using results
- Compare outputs across multiple tools
- Involve subject experts and communities in reviewing findings
- Prompt AI to flag Western-centric assumptions: e.g., prompting to “Include African citations and sources”
Practical tips for responsible use
| 🔒 De-identify data before input Remove names, locations and identifiers from data before upload. Tools: SpaCy (NER) and NICH Chrome Extension. |
| 📁 Control data access When AI tools access organisational systems (e.g., SharePoint), constrain access to specific folders only. |
| 📋 Update informed consent Inform research participants when AI may be used in the analysis of their data. |
| 🗣 Be transparent with participants and stakeholders Communicate openly about how AI is being used in your MEL processes. |
| 💳 Be clear on the differences between paid/enterprise and free versions of tools Choose the option that best meets your privacy needs, using enterprise versions if your organisation has them, as data entered into free tools may be used for model training. You may also opt out in settings where available. |
✏️ Prompt engineering
Prompting well is a core MEL skill. These principles apply across all tools.
- Provide context and specificity
Tell the model who it’s for, what the purpose is and any relevant background before asking your question.
- Give examples of your desired output
Show the format or approach you want — a sample table, a short paragraph — to anchor the model’s response.
- Set constraints
Specify length, format, tone and limits: e.g., “Respond in no more than two pages” or “Do not use bullet points”.
- Assign a persona or expertise area
e.g., “Act as a qualitative researcher with experience in gender analysis.” This shifts the model’s framing and vocabulary.
- Break tasks into smaller steps
Complex tasks work better iteratively rather than in a single large prompt, and each step should be reviewed by a human.
- Ask the model to reason step by step
Requesting visible reasoning reduces errors and makes it easier to spot mistakes before they propagate.
To learn more about the use of AI in evaluation
The workshop highlighted the importance of thinking critically as a sector and as MEL practitioners about our use of AI. You can find out more about the MERL Tech Initiative here, this is a free network with a monthly newsletter, events and working groups. See the Welcome Page for sub-group details.
Look out for Kerry’s forthcoming book on the use of GenAI in evaluation Algorithms to Evidence: Using GenAI in Evaluation Practice, and follow Kerry on LinkedIn for updates.
📚 Useful resources and links
Guidance and strategy
- Integrating AI in Evaluation — World Bank 2025 guidance note, includes prompting tips
- IEG AI Strategy — Independent Evaluation Group’s broader AI strategy document
- AI Model Cards — 5 Things to Know — IAPP explainer on what model cards are and why they matter
Bias and benchmarking
- Bias in AI: Examples and Fixes — Overview of common bias types with model comparisons
- Weval — More trustworthy benchmarking site; includes LMIC language data
- BenchLM & LLM Stats — Treat with caution; reflect big-tech incentives
Technical tools
- AIlyze — AI-assisted qualitative data analysis
- De-identifying data with SpaCy / Python — NER guide for anonymising data before AI input
- *NICH Chrome Extension — Browser-based de-identification using AI-powered entity recognition
- *Thaura — An ethical AI companion tool
Books
- Artificial Intelligence and Evaluation — Nielsen, Rinaldi & Petersson (Taylor & Francis, 2024) — open access; includes a chapter by Kerry Bruce
*mentioned by attendees rather than by facilitators

Category
News & views